Insurance operations
Agents answer underwriting questions from approved documents and draft the paperwork.
Needs approval Bind, cancel, file a claim
 Prashna Labsप्रश्न
Product · Early access
The governance runtime for production AI agents.
A runtime for AI agents that companies can actually trust in production. Every action is identified, traced, and audited, and a person approves anything risky before it runs.
Chain verified · 201 events · no tampering
Who it is for
Agents answer underwriting questions from approved documents and draft the paperwork.
Needs approval Bind, cancel, file a claim
A support agent that resolves requests over the API, with every step traced.
Needs approval Refunds, account changes
Agents that search, read, and summarise, citing where each claim came from.
Needs approval Paid tools, sending results out
How it works
In
Your app
REST API or streaming
Best Agents runtime
Out
Model provider
Tools over MCP
Your documents
Written for every step
Signed, hash-chained audit log · OpenTelemetry traces
Approvals
Binding a policy, cancelling a contract, filing a claim: you decide which actions need approval. The agent stops, shows what it wants to do and the policy that requires a check, and waits for someone to approve or deny it.
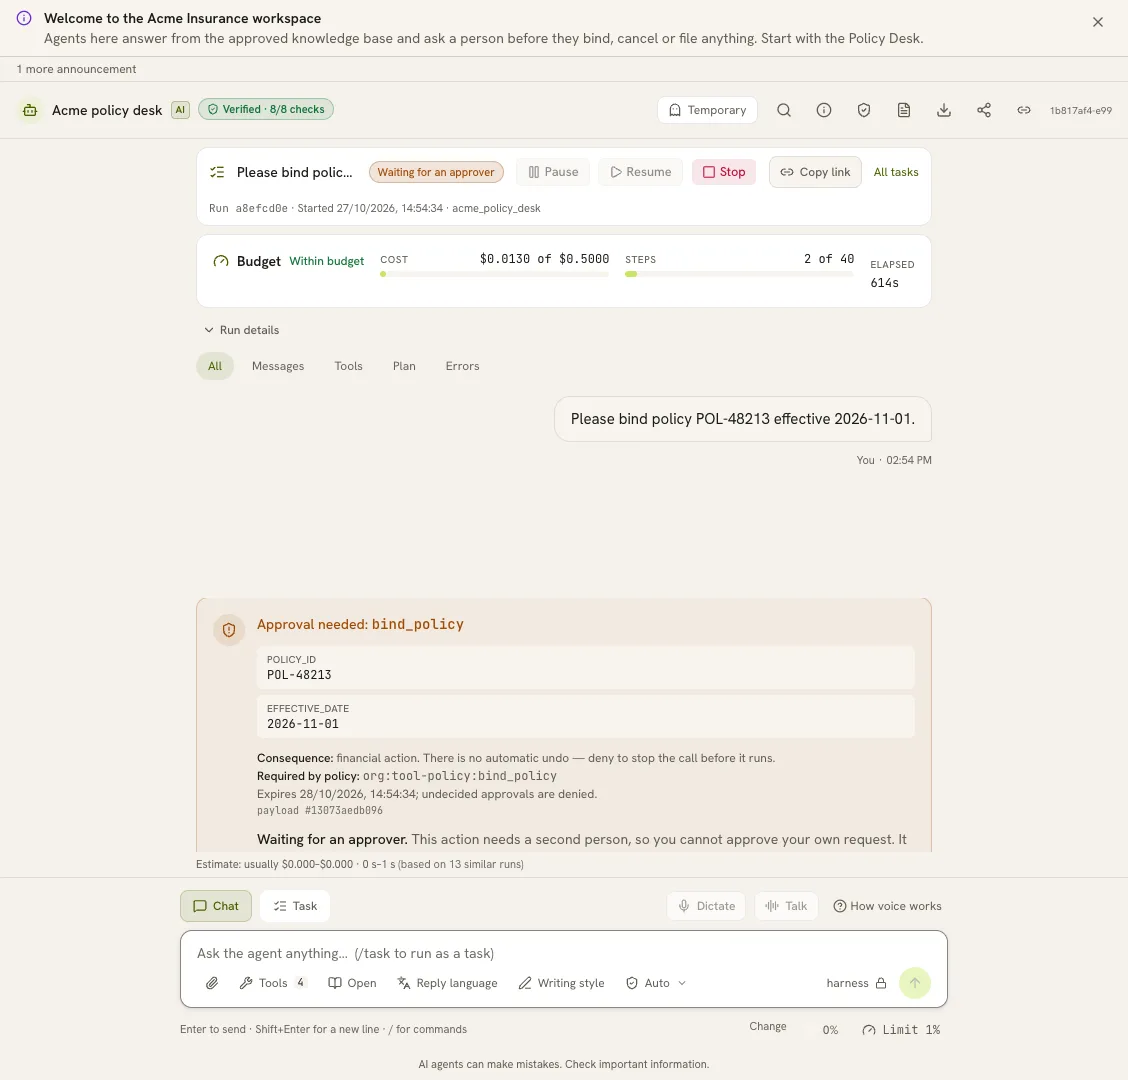
Grounded answers
Agents answer from the knowledge you have approved and cite where each answer came from. Every tool call is checked against policy, and the whole run is visible: messages, tools, plan, and errors.
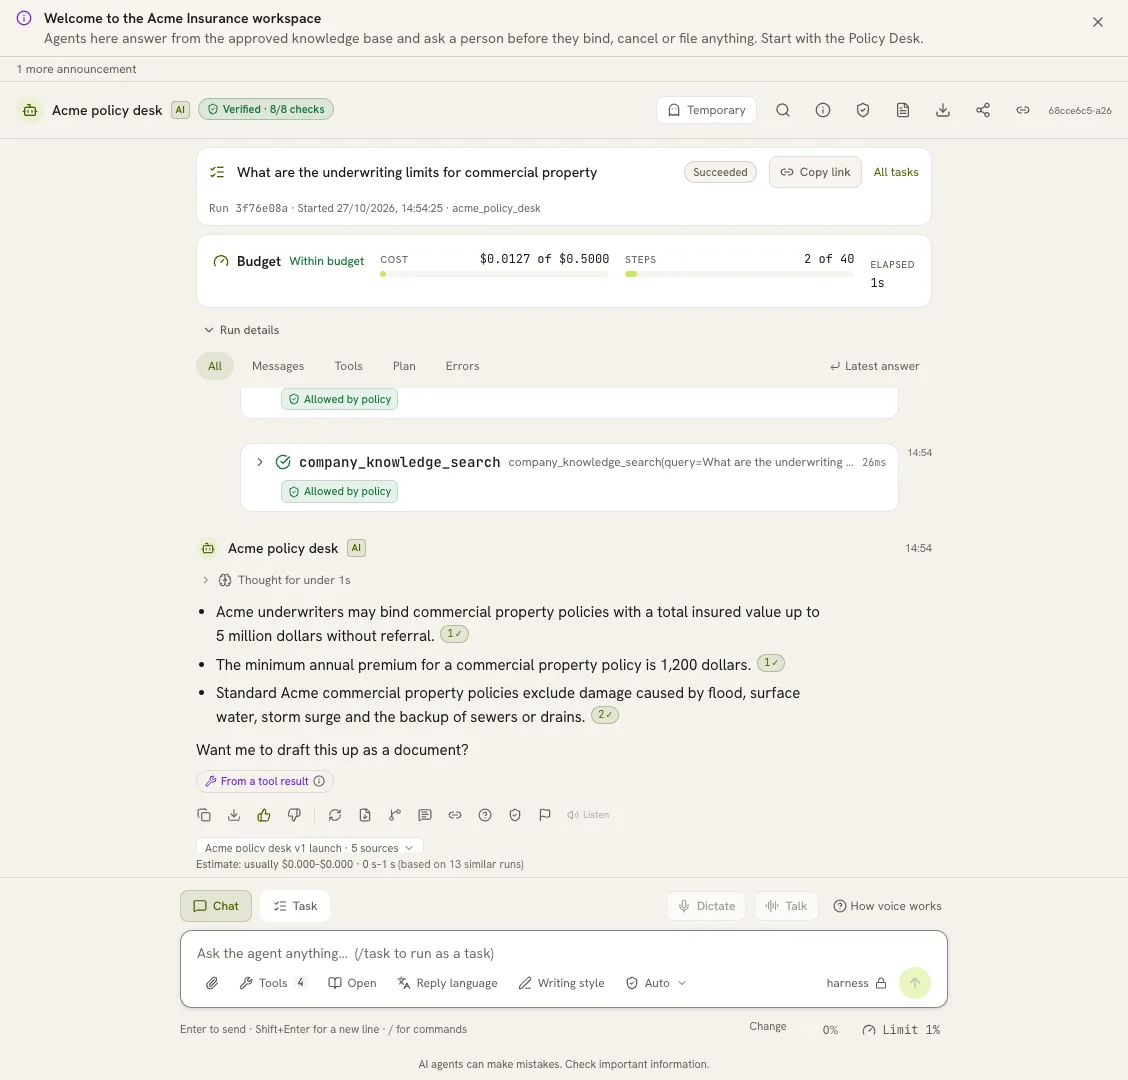
Audit
Every action is tied to an agent identity and written to a hash-chained log with signed checkpoints. Verify the chain in one click and hand auditors a report they can check offline.
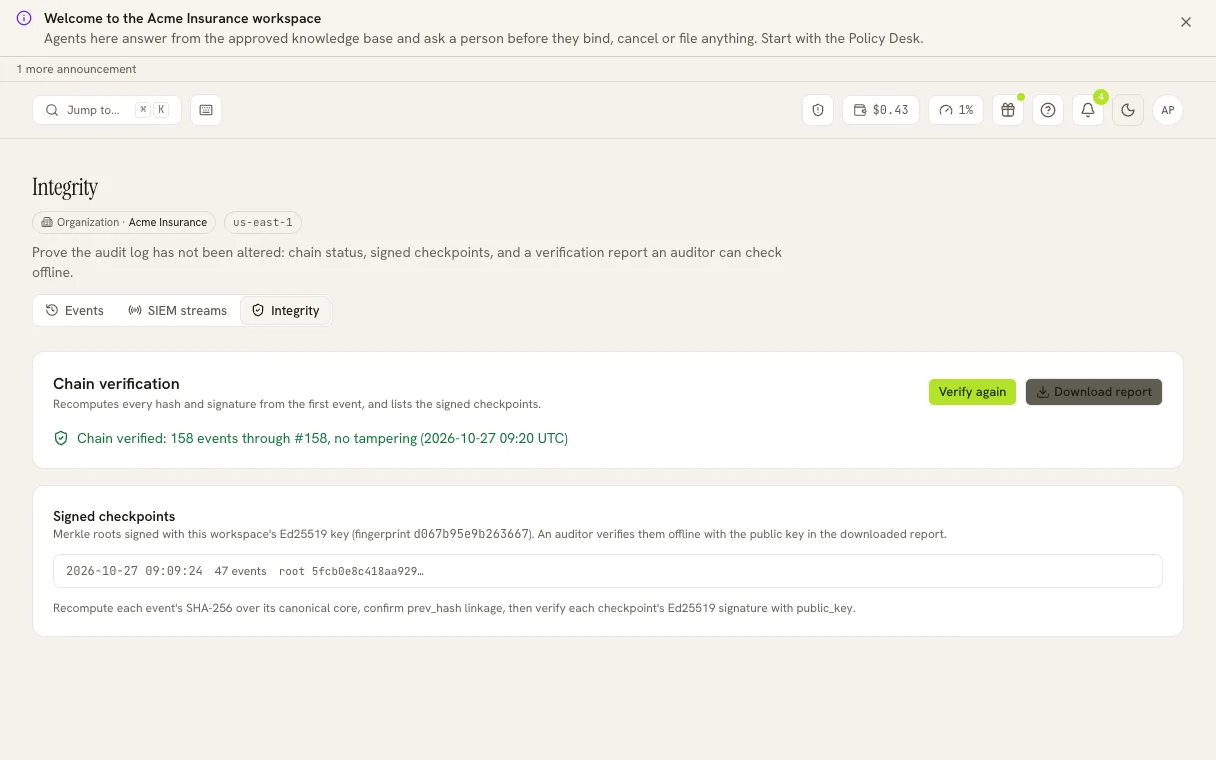
Screens from the demo workspace with sample data.
For developers
Call an agent over the REST API. The agent, user, and tenant you send are attached to every action that follows, so each step in the audit log says who asked for it.
curl -X POST https://your-host/api/v1/agents/support/run \
  -H "Content-Type: application/json" \
  -H "X-Agent-Id: my-agent" \
  -H "X-User-Id: user-1" \
  -H "X-Tenant-Id: tenant-1" \
  -d '{"input": "Help me reset my password"}'
What ships today
Every action carries who ran it, for which user and tenant, so nothing happens anonymously.
agent=policy-desk user=u-1042 tenant=acmeStop an agent, or every agent, immediately. Revoke an identity without redeploying.
kill_switch.engaged runs stopped: allAgent and prompt versions are scored, and only promoted when they pass.
v13 score 0.91 >= gate 0.85 promotedOpenTelemetry spans and structured logs on every run, sent to the tools you already use.
span gen_ai.chat 412ms 1,204 tokensToken budgets and cost limits per run, with durable execution that survives restarts.
budget $0.50 spent $0.03 okConnect external tool servers through an MCP gateway, under the same policy checks.
mcp crm.lookup_customer allowedVersioned skills and YAML-configured agent behaviour per use case, no code plugins.
domains/support.yaml skill v4Data, members, and knowledge are scoped per tenant, and every change is audited.
scope tenant=acme row-level securitySample values shown under each capability.
Compared
| Capability | Best Agents | Tracing-only tools | Build it yourself |
|---|---|---|---|
| See every step of a run | Yes | Yes | You build it |
| Pause a risky action before it runs | Yes | No | You build it |
| Human approval with expiry | Yes | No | You build it |
| Signed, tamper-evident audit log | Yes | No | You build it |
| Kill switch and identity revocation | Yes | No | You build it |
| Evals that gate releases | Yes | Partly | You build it |
Deployment
Not finished yet
Questions
OpenAI by default, and Anthropic is supported. The provider and model are configuration settings. With bring your own key, usage runs on your own account.
Yes. Run it self-hosted with Docker, or embed it as a library inside your own Python service.
You decide which tools need approval. When the agent calls one, the run pauses, shows the arguments and the policy that requires a check, and waits. Approvals expire, and undecided ones are denied.
No. It is built to produce SOC2-oriented evidence from day one: agent identity, OpenTelemetry traces, and signed audit logs. The certification itself is yours to run.
Through the REST API today: run an agent, or stream its output over server-sent events. Slack, Discord, email, webhook, and widget channels are early.
We are in early access. Request a demo and we will talk through pricing for your use case.
Tell us what you want your agents to do, and we will walk you through it in a short call.